1. Introduction
Today we'll go deep into the world of web scraping, concentrating on one of the most popular and broad databases available: IMDB, or the Internet Movie Database. IMDB is a massive internet database that contains information on movies, TV shows, video games, and much more.
Before we start scraping data from IMDB, it's good to learn a bit about a tool called Scrapy. Scrapy helps us collect data from websites easily. It's a tool made for Python, a programming language. You can find the official Scrapy tutorial here to get started with the basics.
At the end of this article, you will be able to fetch your required information about movies and TV shows including Title, Release Date, Cast, Director, Ratings, Genre, Writers, Images, Videos, and more. We will start by analyzing the listing page, then move to the detail page and extract the data we need.
Note
It's common to encounter errors during the scraping process. There is a Common Errors section at the end of this blog for reference. All code used in this project is also available in the GitHub repository here.
2. How to Create a Scrapy Project
Open your terminal and run the following command to create a new Scrapy project. The startproject argument creates a template Scrapy project, and the last part is the name of the project you can set this to whatever you like.
scrapy startproject imdbscraper
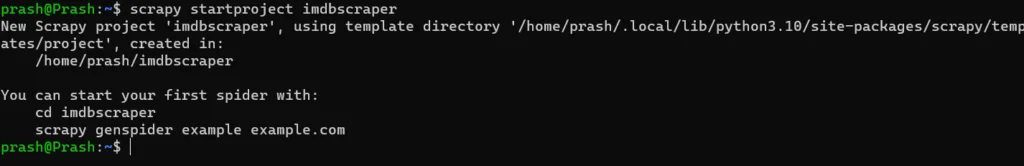
Now navigate into the project folder:
cd imdbscraper
Open the folder in your code editor (VS Code is used here), then create a spider inside the spiders folder using the following command:
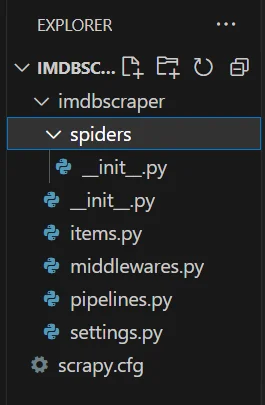
scrapy genspider moviescraper https://www.imdb.com/search/title/?genres=Action&explore=title_type%2Cgenres
This command creates a spider named moviescraper that scrapes the provided URL. A file named moviescraper.py will be created in the spiders folder, which is the file we will be working with.
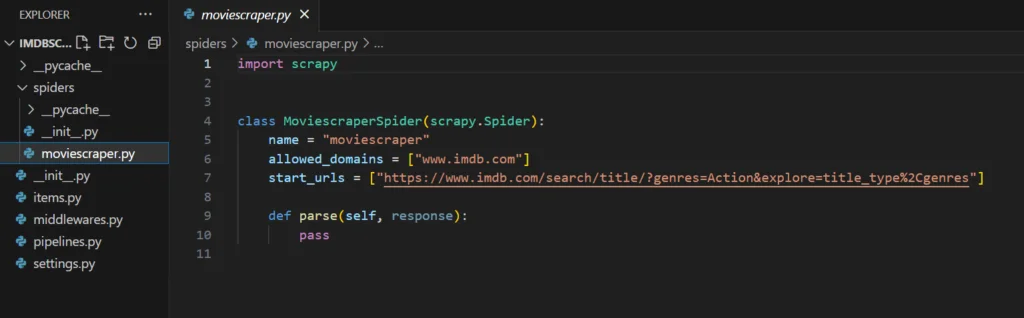
You can also edit the start_urls variable and place the listing URL inside it. Remove the allowed_domains line for this scraping project. The spider will send a request to the URL, get the response, and pass it to the parse function, which receives the full HTML of the page.
3. Exploring the Webpages (for Detail Page)
Analyzing the Listing Page
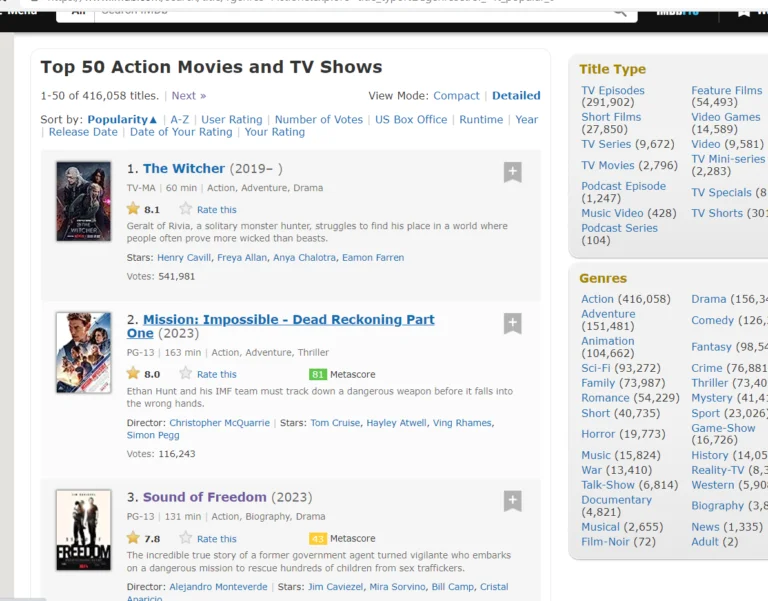
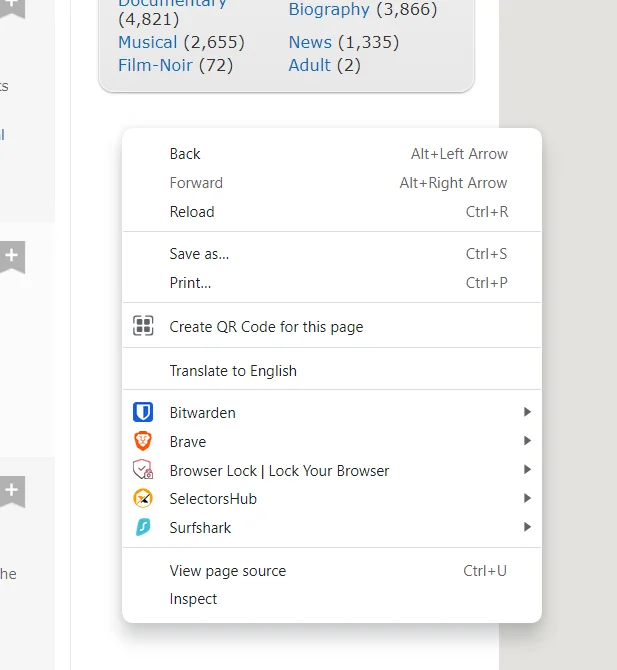
The listing page contains links to various media (movies, TV shows, games). In this article we use the Action genre listing page. Right-click on any empty area of the webpage to access the two key tools:
- View Page Source: Loads the full HTML in a new tab exactly as it is served by the website's servers.
- Inspect: Shows the HTML in an interactive panel, allowing you to click on elements and see where they live in the DOM tree.
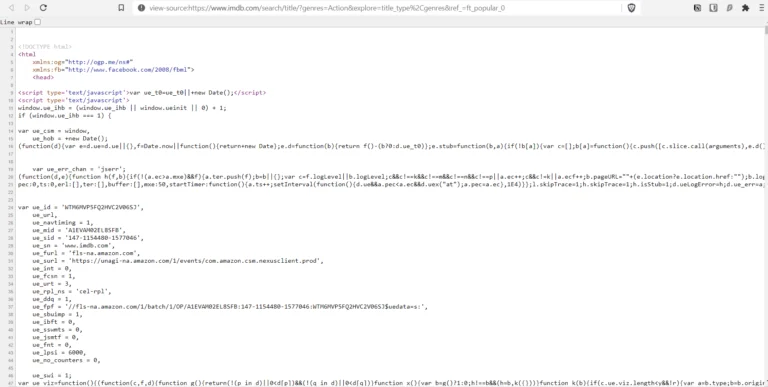
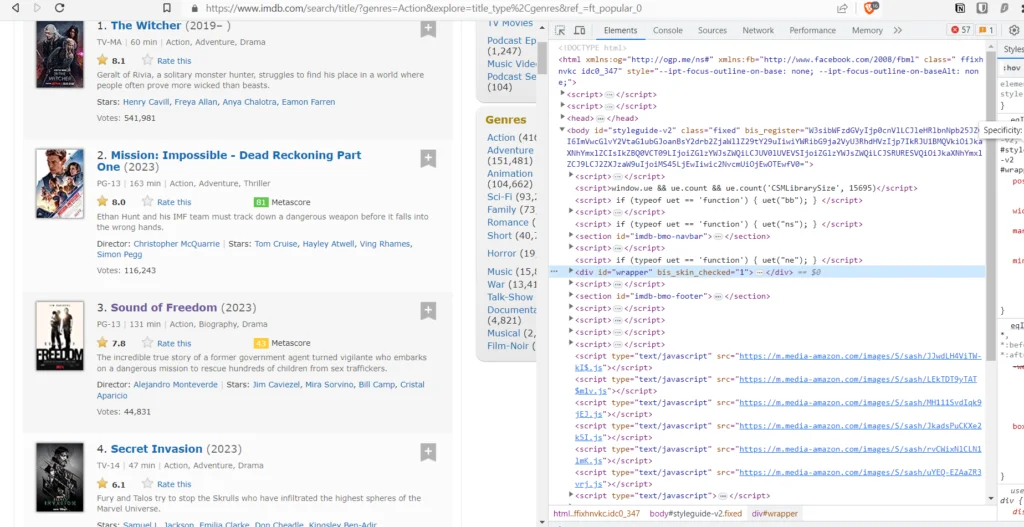
To find the link for a detail page, click the inspector icon in the top corner of the inspect tab, then hover over and click a movie title. The inspect tab will highlight the exact HTML element for that title, including its href link.
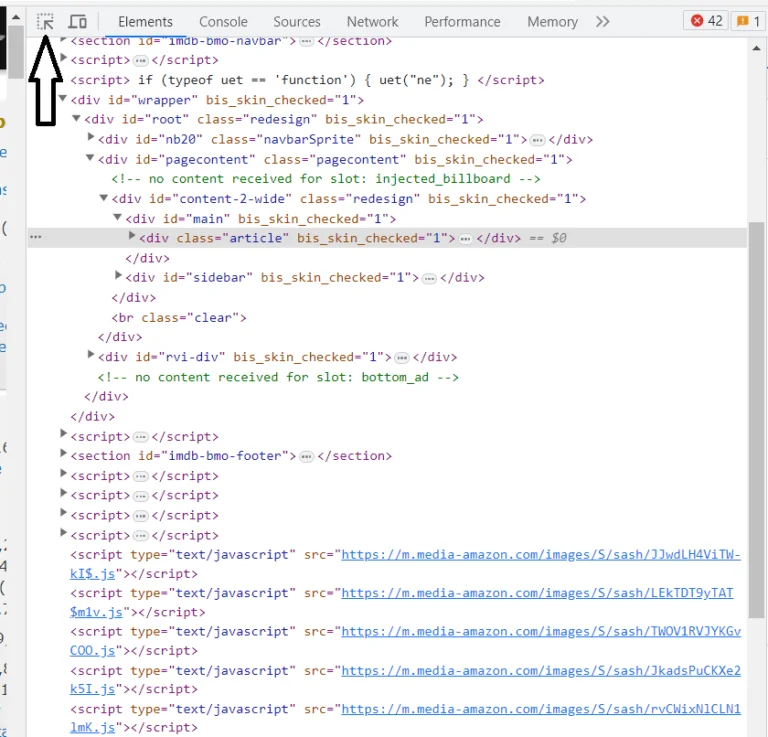
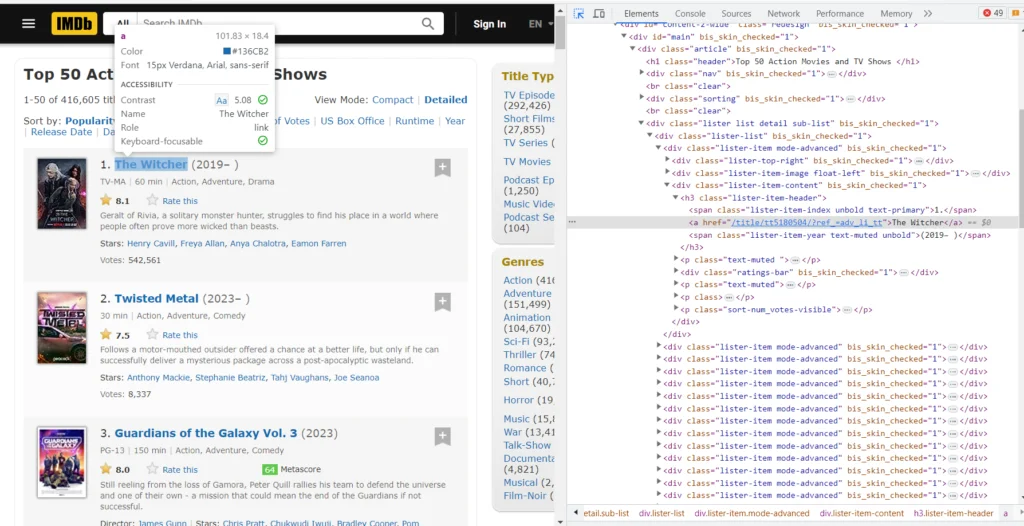
From analyzing the listing page, we can determine:
- All links are inside an 'a' tag, which is inside an 'h3' tag with class 'lister-item-header', which is inside a 'div' tag with class 'lister-item-content'.
- The full detail page URL is constructed as 'https://imdb.com' + the href value of the link.
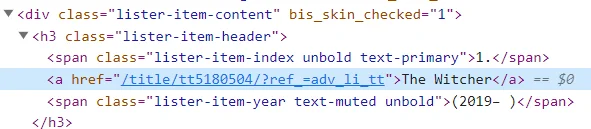
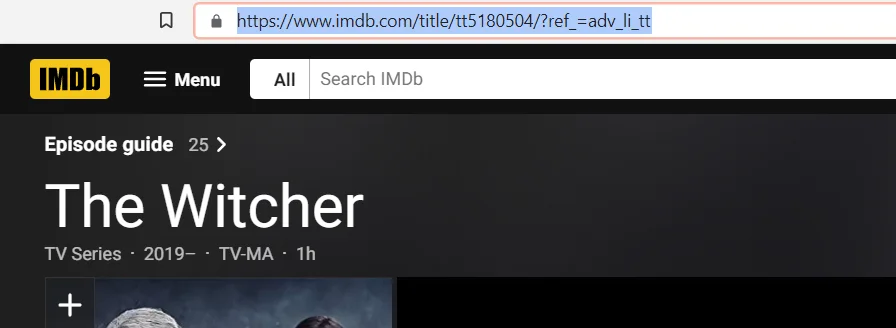
4. Coding Part I Request to Detail Page
Our objective here is to collect the URLs of all movie detail pages from the listing page and send requests to each one. We do this inside the parse function.
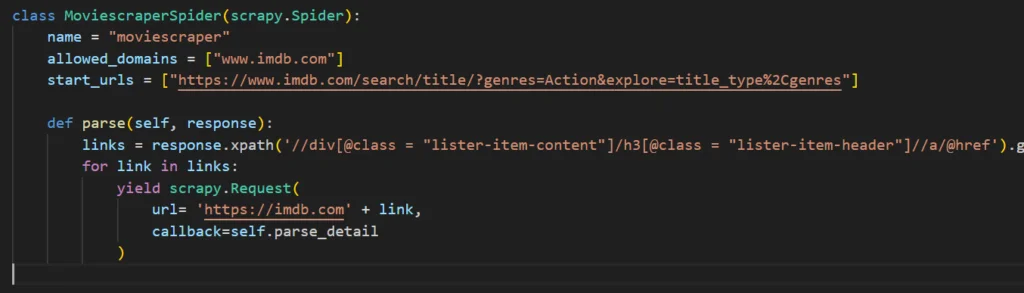
First, grab all the detail page links using XPath:
links = response.xpath('//div[@class = "lister-item-content"]/h3[@class = "lister-item-header"]//a/@href').getall()This XPath selects all div elements with class lister-item-content, navigates inside to find the h3 with class lister-item-header, and grabs the href attribute of the a tag inside it. getall() returns a list of all matched values.
XPath Tip
XPath is a crucial skill when working with Scrapy. It helps you navigate through the HTML structure of a web page to pinpoint and extract exactly the data you need. The official Scrapy XPath Documentation is a great resource to master this skill.
Now loop through the links and send a request to each detail page, passing the response to a parse_details callback function:
for link in links:
    yield scrapy.Request(
        url= 'https://imdb.com' + link,
        callback=self.parse_details
    )
5. Analyzing the Listing Page & Coding for Next Page (Pagination)
Now we need to handle pagination so the spider automatically moves to the next page and repeats the same steps.
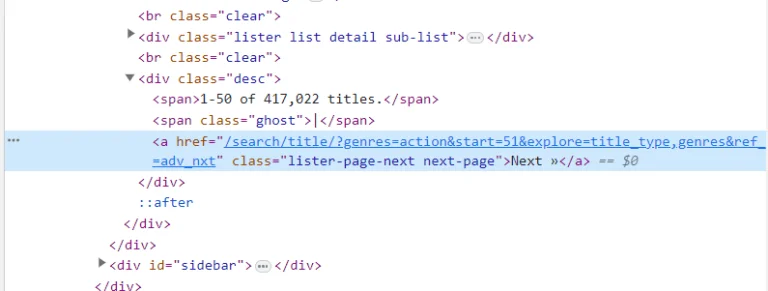
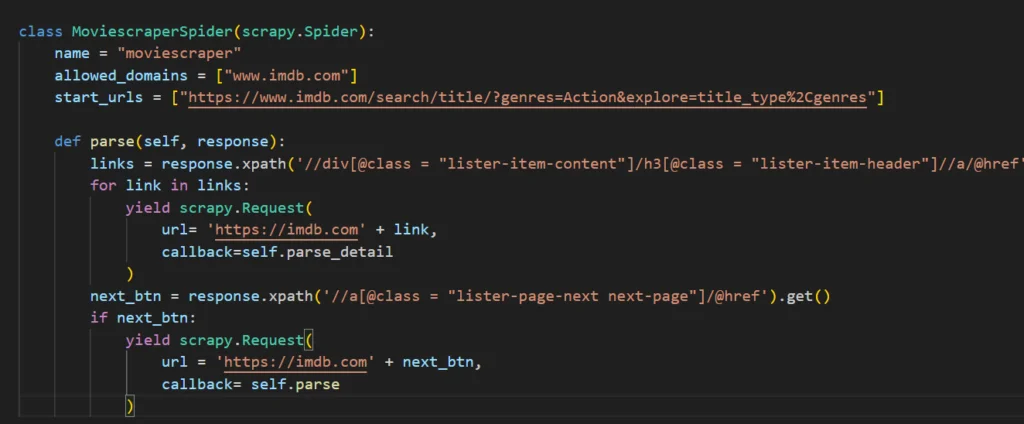
The next button is an a tag with the class lister-page-next next-page. We select it, grab its href, and if it exists, send another request back to the parse function to process the next page:
next_btn = response.xpath('//a[@class = "lister-page-next next-page"]/@href').get()
if next_btn:
    yield scrapy.Request(
        url = 'https://imdb.com' + next_btn,
        callback= self.parse
    )
6. Analyzing the Detail Page & Coding to Extract Information
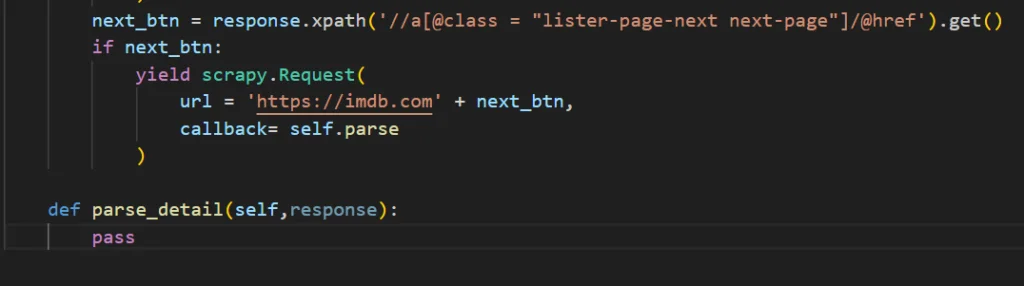
Create a function named parse_details that takes response as a parameter. We will analyze each field and write the corresponding XPath selector.
Title
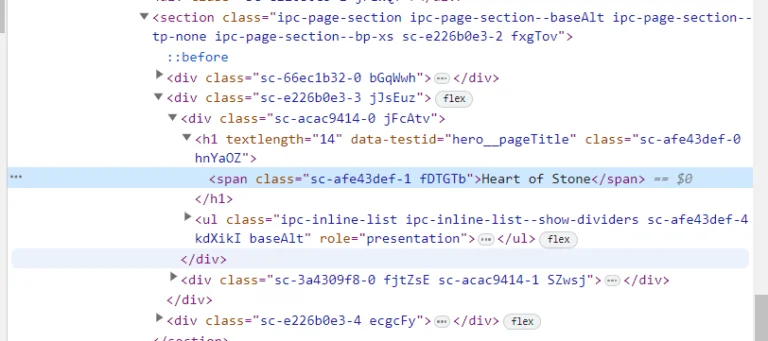
The title is inside a span tag inside an h1 tag with the data-testid attribute hero__pageTitle. We use the data-testid instead of a class name because class names are dynamic and may change.
title = response.xpath('//h1[@data-testid = "hero__pageTitle"]/span/text()').get()Rating
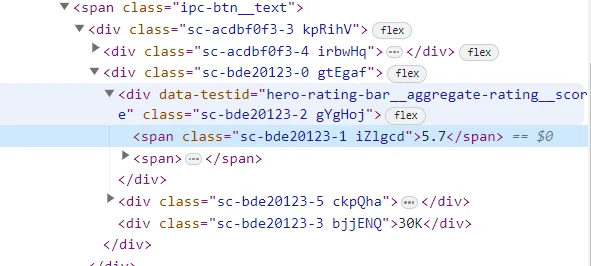
rating_score = response.xpath('//div[@data-testid= "hero-rating-bar__aggregate-rating__score"]/span/text()').get()Summary
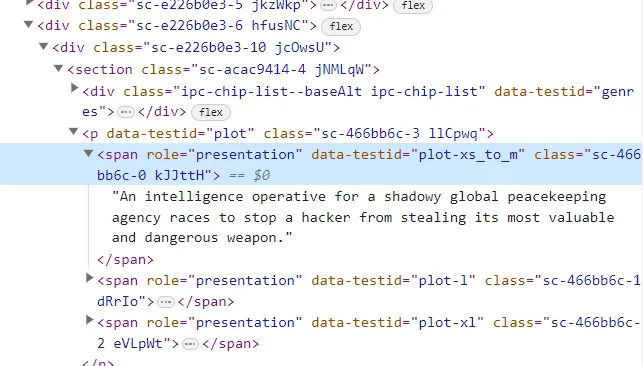
summary = response.xpath('//span[@data-testid="plot-xl"]/text()').get()Director, Writers & Stars
There is no specific class name for director and cast details, so we first select the parent container and then use text-based XPath to locate each role:
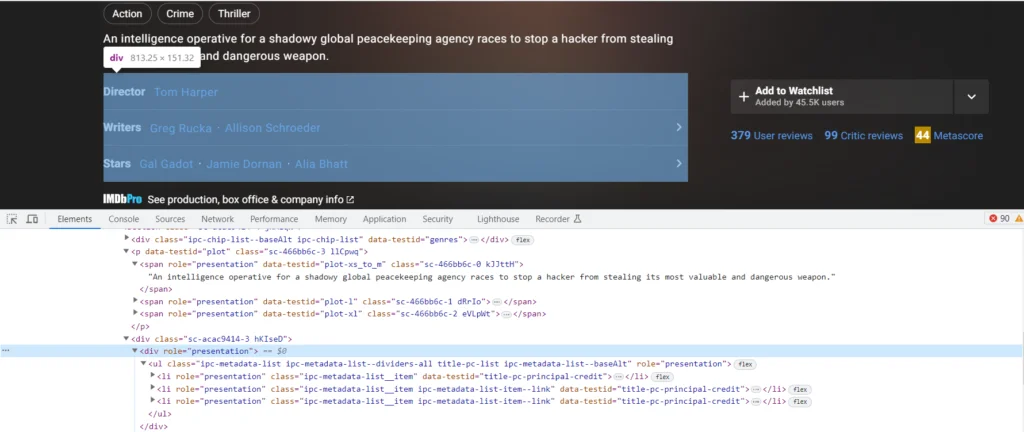
cast_details = response.xpath('//div[@role = "presentation"]')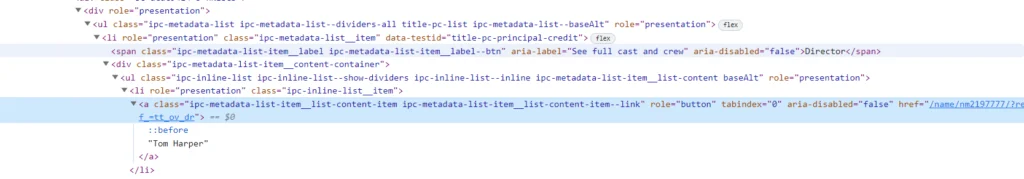
The director's name is inside an a tag, nested inside a li tag, inside a div that is a sibling of the spancontaining the text "Director". The same pattern applies for Writers and Stars:
director = cast_details.xpath('//li[@role="presentation"]*/[text() ="Director"]/following-sibling::div//li[@role= "presentation"]/a/text()').get()

writers = cast_details.xpath('//li[@role="presentation"]*/[text() ="Writer"]/following-sibling::div//li[@role="presentation"]/a/text()').getall()

stars = cast_details.xpath('//li[@role="presentation"]*/[text() ="Stars"]/following-sibling::div//li[@role= "presentation"]/a/text()').getall()
Writers and stars may appear repeated in the list. To keep only unique values:
writer_newlist = []
for i in writers:
    if i not in writer_newlist:
        writer_newlist.append(i)

stars_newlist = []
for i in stars:
    if i not in stars_newlist:
        stars_newlist.append(i)
Now yield all the collected data as a dictionary:
yield {
    'Url'     : response.url,
    'Title'   : title,
    'Rating'  : rating_score,
    'Summary' : summary,
    'Director': director,
    'Writer'  : writer_newlist,
    'Stars'   : stars_newlist
}
7. Running the Scrapy Code
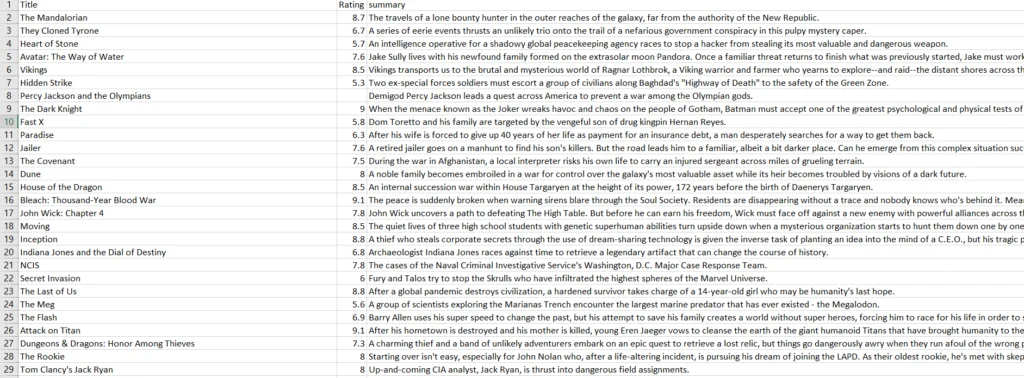
Open your terminal in the project folder and run the following command. The -O data.csv flag tells Scrapy to output the scraped data into a CSV file named data.csv.
scrapy crawl moviescraper -O data.csv
Your spider is now running and collecting data. Check the output file to confirm that the right information is being extracted. Hit Ctrl + C to stop scraping at any time.
8. Conclusion
You have successfully scraped data from IMDB using Python and Scrapy. Congratulations mission accomplished! If you have any doubts or problems, feel free to leave a comment. Cheers!
9. Common Errors
- 1Sometimes a scraper has to follow robots.txt, which is a guideline for crawlers. You can set ROBOTSTXT_OBEY to False in your settings file if you encounter issues. Note that while it may be legal not to follow these guidelines, it is generally considered unethical.
- 2A 403 or 302 status code error is usually caused by missing headers, cookies, or request body. You can add the required headers when making your requests to resolve this.
- 3If the HTML structure of a page changes, the scraper may break. In that case, inspect the updated page and rewrite the relevant XPath selectors.
Need Custom Solutions?
We are a data scraping and mining company. If you want to contact us for any scraping work, feel free to reach out at info@parsedom.com.